Overview
StyleInstructCaps is a large-scale benchmark for instruction-following speaking-style captioning with audio language models. We release StyleInstructCapsDB on Hugging Face — over one million utterances with rich style captions, six evaluation subsets, and an official toolkit spanning eight evaluation axes: metadata groundedness, hallucination, instruction following, speaker verification, speaker consistency, unseen-dataset generalization, out-of-domain prompts, and multi-model clustering analysis.
Audio is not redistributed; each row provides a relative_audio_path resolved against upstream corpora
(Emilia, VoxCeleb, VCTK, EARS, Expresso, GigaSpeech). Evaluation uses Qwen3-32B as LLM-as-judge and e5-base-v2 for speaker metrics.
Benchmark Overview
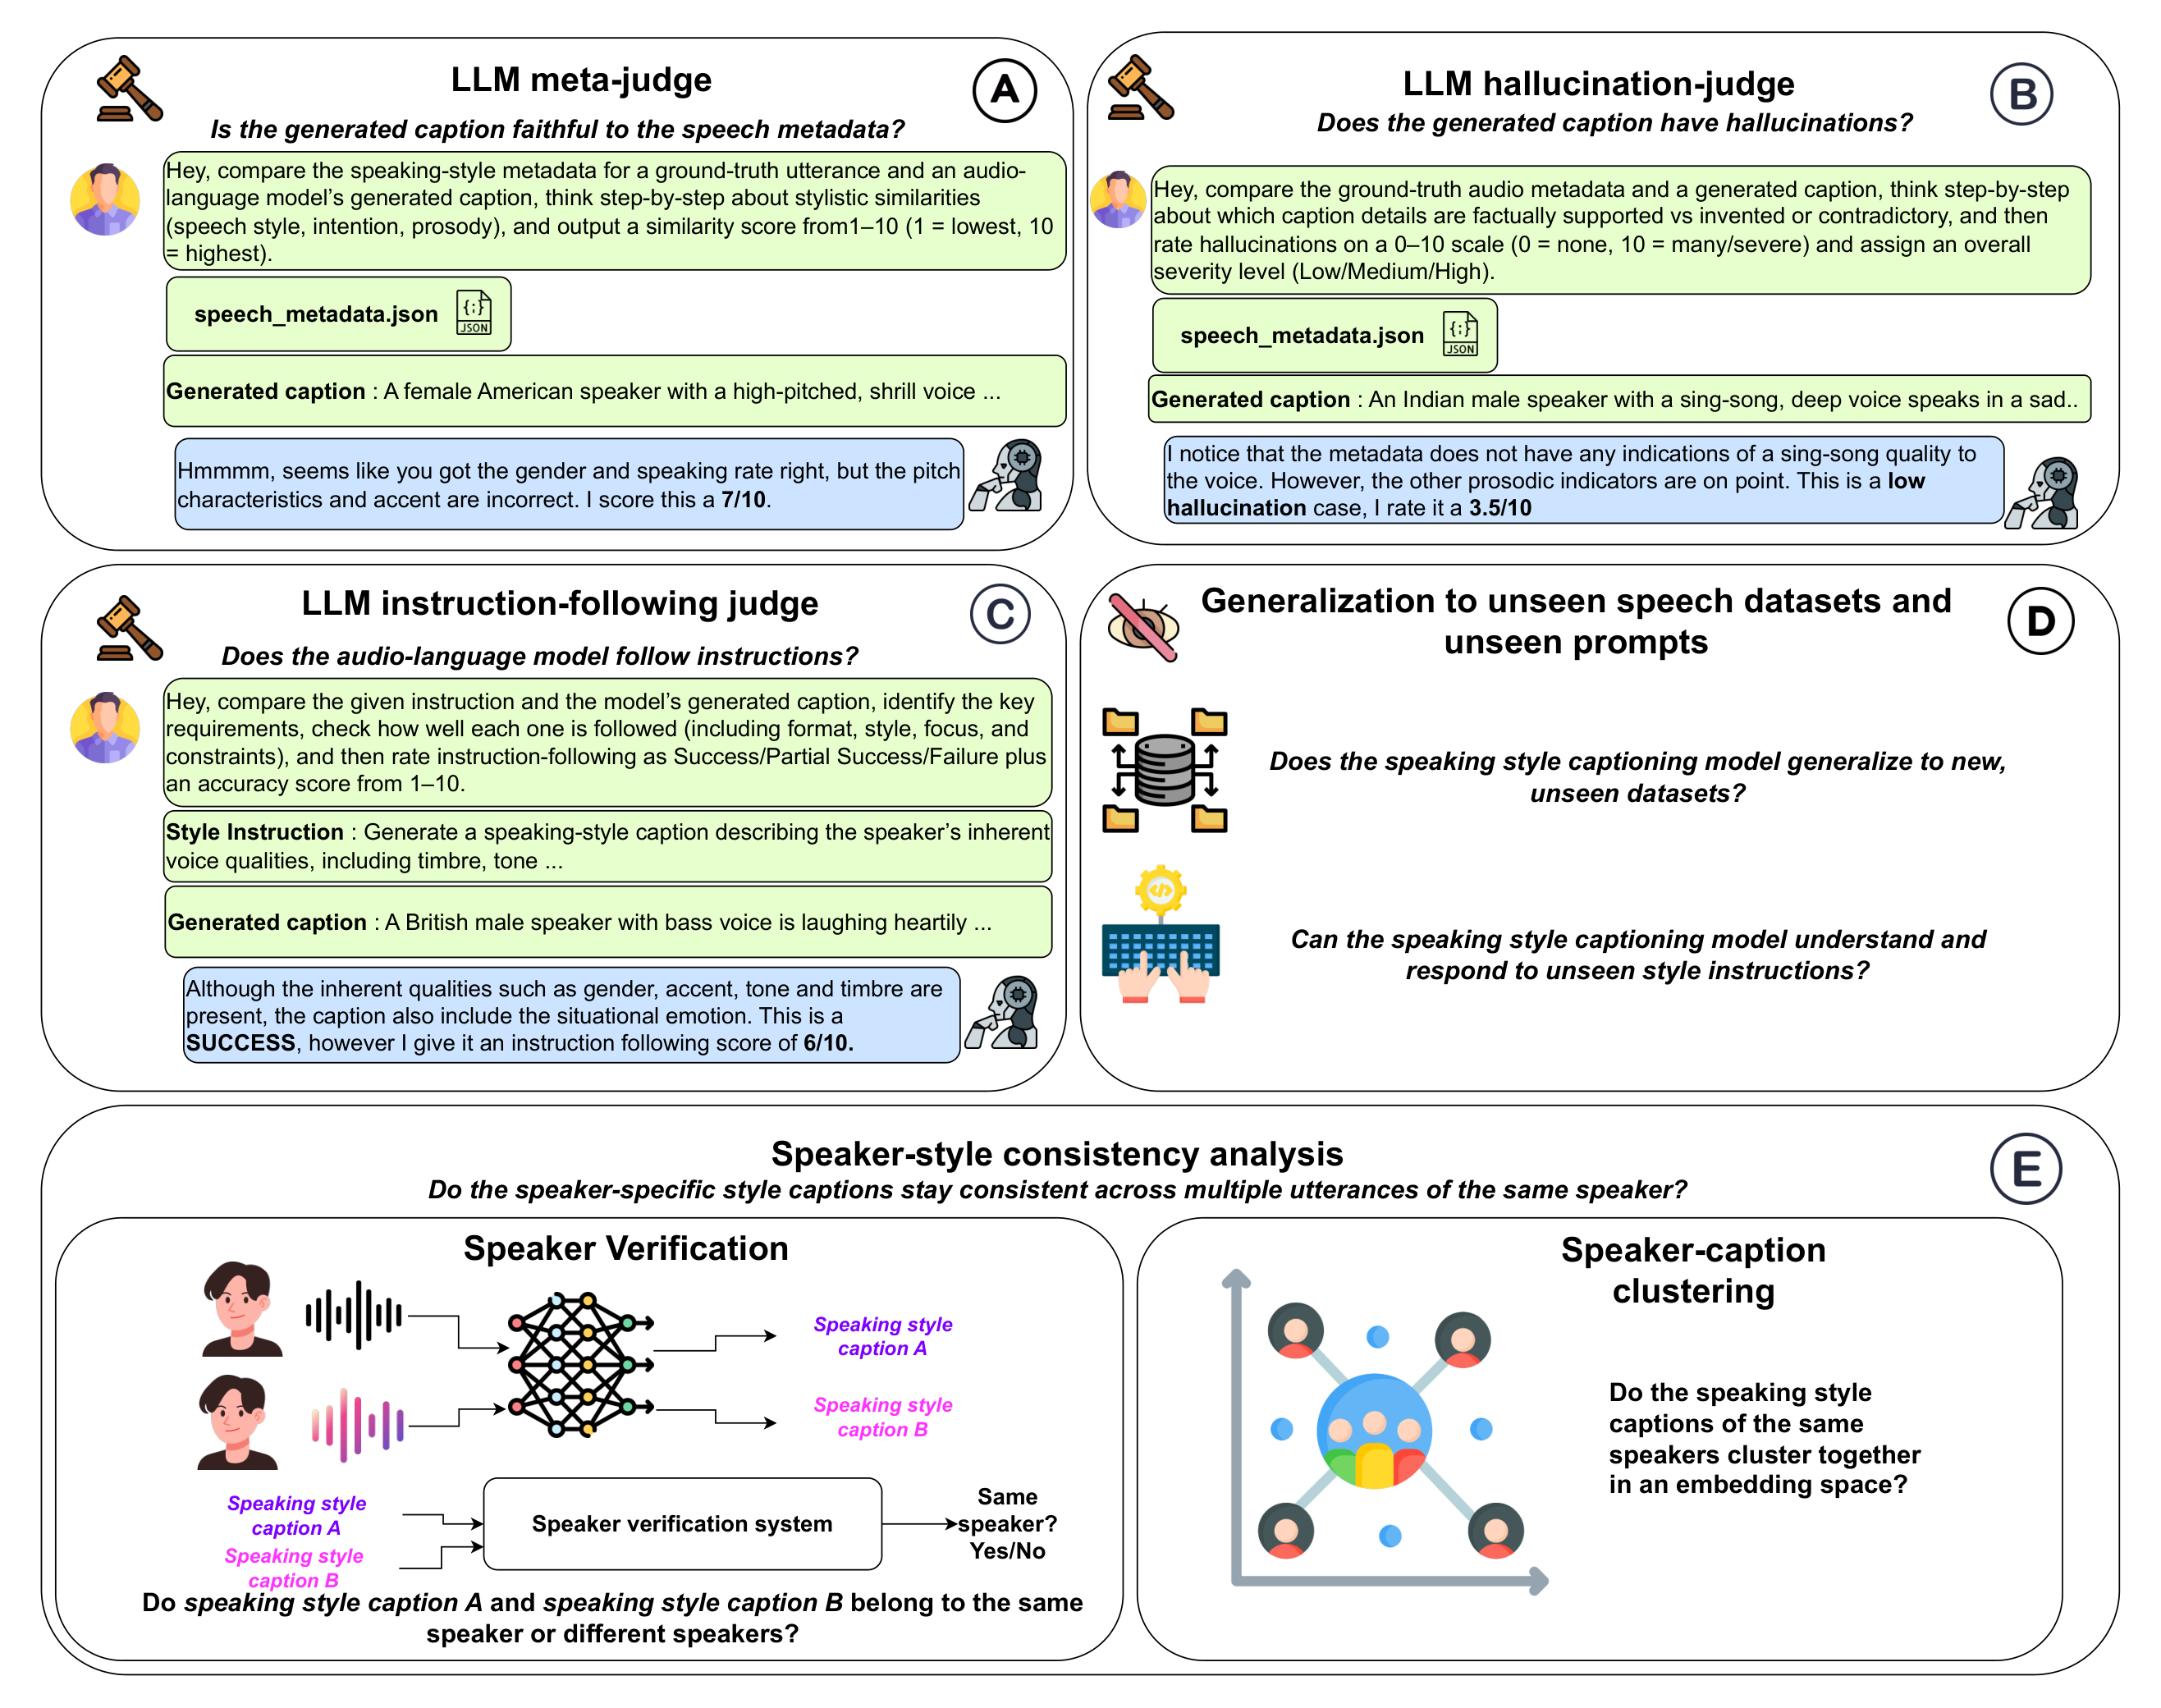 Open the figure as PDF
Overview of the StyleInstructCaps benchmark: dataset construction, instruction-following style captioning, and multi-axis evaluation on StyleInstructCaps-MetaSet and speaker-consistency splits.
Evaluation Toolkit
The official evaluation repository provides standalone scripts for all eight axes. Load subsets from StyleInstructCaps/StyleInstructCapsDB:
| Axis | Metric | Dataset config |
|---|---|---|
| 1 | Metadata groundedness | StyleInstructCaps-MetaSet |
| 2 | Hallucination | StyleInstructCaps-MetaSet |
| 3 | Instruction following | StyleInstructCaps-MetaSet |
| 4 | Speaker caption verification | VCTK_speaker_prompts |
| 5 | Speaker consistency | VCTK_speaker_prompts |
| 6 | Unseen eval (groundedness + hallucination + IF) | Gigaspeech_SpeechCraft_captions |
| 7 | OOD prompt analysis (IF only) | VCTK_unseen_prompts |
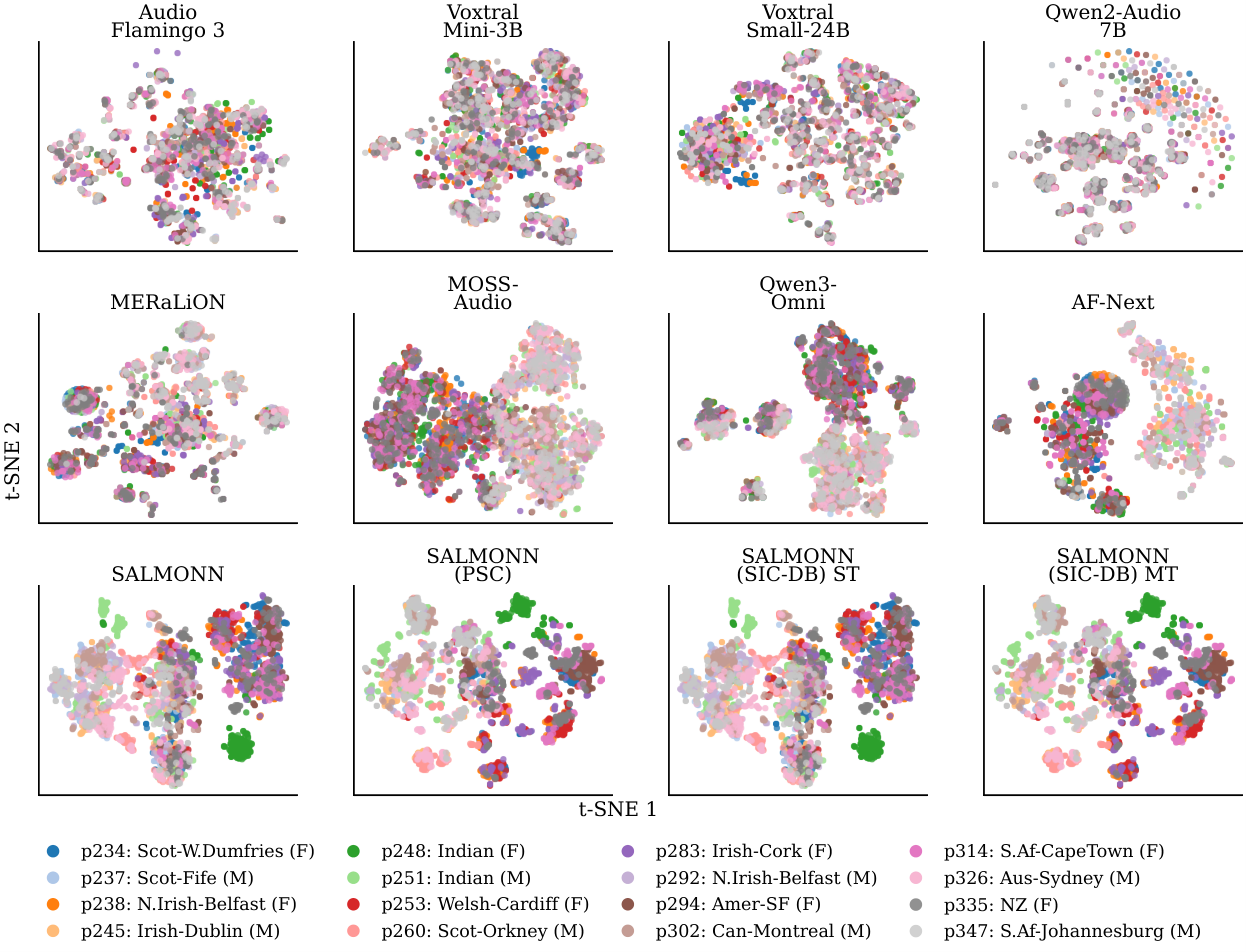
| 8 | Speaker description consistency (clustering plots) | VCTK_speaker_prompts (multi-model) |
Main Results
Table 1
Metadata groundedness, hallucination severity, and instruction-following performance evaluated on StyleInstructCaps-MetaSet. Blue shading indicates relative performance for scalar metrics.
| Model | LLM metadata groundedness | LLM hallucination severity (%) | Instruction following | ||||
|---|---|---|---|---|---|---|---|
| Meta score ↑ | Hall. ↓ | Low | Mid | High | IFA score ↑ | IFA rate (%) ↑ | |
| Oracle Caption (PSC) | 9.93 | 0.07 | 99.5 | 0.5 | 0.0 | — | — |
| Oracle caption (SIC-DB) | 9.93 | 0.04 | 99.8 | 0.2 | 0.0 | 8.48 | 71.3 |
| Audio-Flamingo-3 | 5.69 | 6.07 | 15.4 | 20.7 | 63.8 | 8.21 | 62.4 |
| Voxtral-Mini-3B | 7.56 | 3.12 | 48.6 | 35.0 | 16.4 | 8.15 | 68.0 |
| Voxtral-Small-24B | 7.20 | 1.58 | 73.5 | 16.8 | 9.7 | 7.51 | 67.8 |
| Qwen2-Audio-7B-Instruct | 5.73 | 5.58 | 19.1 | 27.9 | 53.0 | 6.58 | 53.6 |
| MERaLiON-AudioLLM | 6.57 | 1.25 | 81.8 | 10.6 | 7.6 | 6.11 | 27.7 |
| MOSS-Audio | 9.10 | 4.54 | 21.8 | 45.4 | 32.7 | 8.82 | 82.8 |
| Qwen3-Omni | 6.77 | 2.85 | 51.2 | 30.6 | 18.2 | 7.99 | 74.0 |
| Audio-Flamingo-next | 9.18 | 4.82 | 19.4 | 38.9 | 41.7 | 7.59 | 48.5 |
| SALMONN | 7.85 | 3.63 | 42.1 | 28.3 | 29.5 | 7.50 | 58.5 |
| SALMONN (PSC) | 9.24 | 4.77 | 21.2 | 46.3 | 32.5 | 7.98 | 52.9 |
| SALMONN (SIC-DB) - ST | 9.32 | 3.88 | 35.2 | 37.3 | 27.4 | 8.37 | 65.6 |
| SALMONN (SIC-DB) - MT | 9.32 | 3.43 | 41.3 | 38.2 | 20.5 | 8.62 | 75.0 |
Table 2
Speaker-style consistency evaluation using clustering and verification metrics on the ID-balanced and UD-VCTK sets. Darker shading indicates better performance per column. Higher is better for ARI, NMI, Purity, InterSep, and AUC; lower is better for EER.
| Model | ID-balanced | UD-VCTK | ||||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| ARI ↑ | NMI ↑ | Purity ↑ | InterSep ↑ | EER ↓ | AUC ↑ | ARI ↑ | NMI ↑ | Purity ↑ | InterSep ↑ | EER ↓ | AUC ↑ | |
| Audio-Flamingo-3 | 0.009 | 0.046 | 0.100 | 0.046 | 0.476 | 0.532 | 0.011 | 0.048 | 0.121 | 0.057 | 0.463 | 0.556 |
| Voxtral-Mini-3B | 0.033 | 0.122 | 0.152 | 0.133 | 0.399 | 0.643 | 0.003 | 0.028 | 0.103 | 0.063 | 0.486 | 0.519 |
| Voxtral-Small-24B | 0.067 | 0.182 | 0.186 | 0.157 | 0.363 | 0.674 | 0.011 | 0.052 | 0.119 | 0.076 | 0.480 | 0.532 |
| Qwen2-Audio-7B-Instruct | -0.002 | 0.010 | 0.072 | 0.026 | 0.498 | 0.499 | -0.002 | 0.007 | 0.083 | 0.025 | 0.496 | 0.498 |
| MERaLiON-AudioLLM | 0.081 | 0.276 | 0.213 | 0.233 | 0.428 | 0.604 | 0.039 | 0.146 | 0.167 | 0.169 | 0.476 | 0.534 |
| MOSS-Audio | 0.191 | 0.381 | 0.347 | 0.221 | 0.282 | 0.792 | 0.076 | 0.228 | 0.186 | 0.175 | 0.319 | 0.755 |
| Qwen3-Omni | 0.152 | 0.297 | 0.243 | 0.204 | 0.376 | 0.630 | 0.069 | 0.216 | 0.184 | 0.165 | 0.311 | 0.734 |
| Audio-Flamingo-next | 0.113 | 0.318 | 0.242 | 0.227 | 0.348 | 0.717 | 0.086 | 0.264 | 0.187 | 0.212 | 0.385 | 0.673 |
| SALMONN | 0.351 | 0.598 | 0.511 | 0.290 | 0.225 | 0.854 | 0.145 | 0.324 | 0.303 | 0.205 | 0.320 | 0.749 |
| SALMONN (PSC) | 0.297 | 0.541 | 0.491 | 0.271 | 0.231 | 0.861 | 0.157 | 0.340 | 0.312 | 0.209 | 0.320 | 0.711 |
| SALMONN (SIC-DB) - ST | 0.363 | 0.577 | 0.508 | 0.284 | 0.214 | 0.876 | 0.145 | 0.324 | 0.303 | 0.205 | 0.320 | 0.749 |
| SALMONN (SIC-DB) - MT | 0.357 | 0.590 | 0.517 | 0.279 | 0.212 | 0.876 | 0.156 | 0.341 | 0.298 | 0.222 | 0.282 | 0.795 |
Table 3
Speaker description verification results on VCTK (10 prompts per speaker). Higher AUC is better; lower EER and minDCF are better.
| Model | EER ↓ | AUC ↑ | minDCF ↓ |
|---|---|---|---|
| Audio-Flamingo-3 | 0.462917 | 0.556000 | 0.025563 |
| Voxtral-Mini-3B | 0.485625 | 0.519186 | 0.009994 |
| Voxtral-Small-24B | 0.479792 | 0.531450 | 0.010206 |
| Qwen2-Audio-7B-Instruct | 0.496250 | 0.497724 | 0.048633 |
| MERaLiON-AudioLLM | 0.476250 | 0.534108 | 0.023596 |
| MOSS-Audio | 0.319375 | 0.755114 | 0.010185 |
| Qwen3-Omni | 0.311250 | 0.734208 | 0.010396 |
| Audio-Flamingo-next | 0.384583 | 0.673539 | 0.031281 |
| SALMONN | 0.320417 | 0.749198 | 0.009960 |
| SALMONN (PSC) | 0.281667 | 0.795312 | 0.010169 |
| SALMONN (SIC-DB) - ST | 0.264375 | 0.831516 | 0.009898 |
| SALMONN (SIC-DB) - MT | 0.281667 | 0.795312 | 0.010169 |
Speaker description consistency (Axis 8)
t-SNE visualization for multi-model speaker clustering on VCTK. This axis evaluates whether speaker descriptions remain consistent across prompts and examples.